MoroccoMA
How a browser speed test turns requests into a result
A speed test observes a path, not an isolated subscription
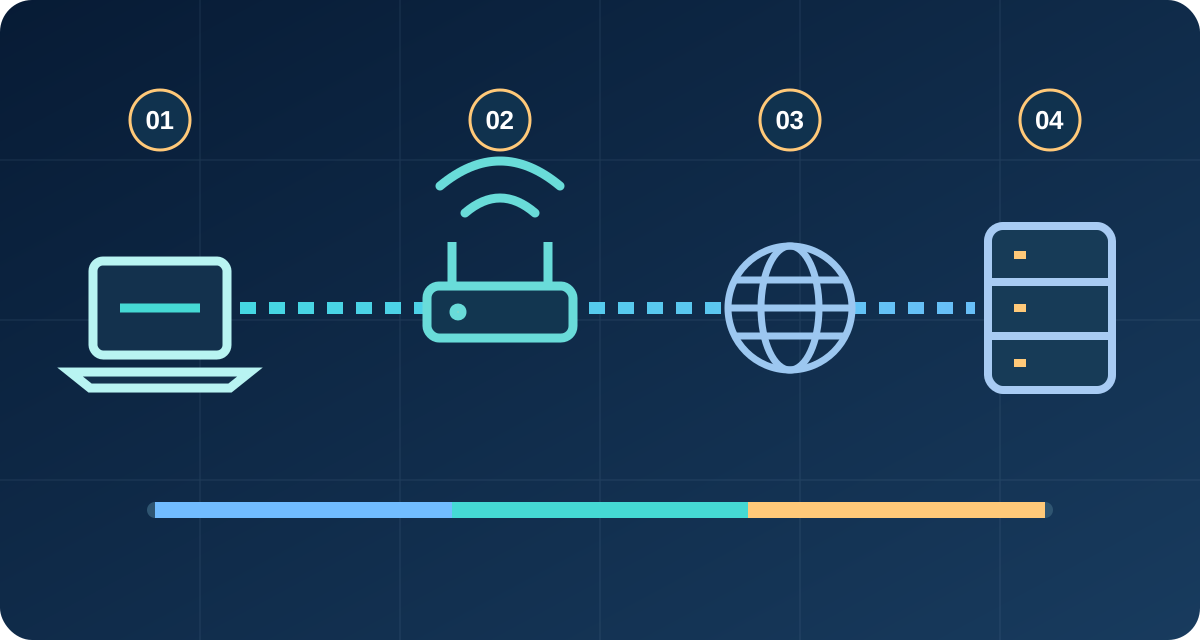
×The browser cannot directly read a universal value called your internet speed. It has to exchange information with another service and measure what happens. The observation includes the device's work, its local connection, the access network, intermediate routing and the remote endpoint. The subscription is one part of that path, but the measurement cannot automatically separate its contribution from every other component.
A hypothetical laptop on a weak wireless link can report less throughput than another device on the same subscription because the local conditions differ. Conversely, a remote application can perform poorly while the measurement endpoint responds well. Both results can be real. The first principle is therefore scope: a result describes the tested path under the tested conditions. That does not make it useless for evaluating a subscription. It means you need a sensible baseline, such as an authorized wired comparison and consistent device, before attributing a limit to the provider. This guide explains the mechanics so you can choose such comparisons and avoid asking one browser observation to prove more than its requests actually measured.
Requests must reach a destination before they can be measured
×A browser request involves more than the payload alone. Depending on what is already established, the browser may need name resolution, a connection and security negotiation before useful data is exchanged. Reusing an existing connection can change those costs for later requests. The receiving service also handles the request, while the browser schedules its own processing of the response.
This is why a very small exchange and a long transfer can tell different stories. A hypothetical first request might spend a noticeable share of its interval establishing communication, whereas a larger subsequent transfer spreads setup costs across more data. A test needs a defined method for which intervals and samples feed its summary. InternetSpeedGeo uses the Cloudflare library for the full measurement rather than pretending every elapsed interval is interchangeable. The separate ping page intentionally times a broader HTTP request and response handling interval to the hosting destination. When two tools disagree, compare their destinations and timing definitions before assuming the underlying network changed. The word speed alone does not identify whether a tool is describing setup, response delay or sustained payload delivery.
The current timeline has three bounded phases
×The full interface runs latency, download and upload in sequence, each in a window of approximately ten seconds. The overall visible sequence is about thirty seconds. Each phase starts a Cloudflare measurement engine with a finite configuration for that phase. Its available summary can update while requests run, and the phase deadline determines when the interface accepts a valid phase summary and moves on.
A finite request set can finish before its displayed window ends. The timer is therefore a user interface and deadline structure, not proof of uninterrupted transfer for every displayed second. This distinction is especially noticeable when a fast connection completes its requests quickly. Do not assume that a steady gauge during the remaining display time means new bytes continue arriving at that exact rate. At the deadline, a required phase needs a finite positive measurement. If it has no such value, the run cannot become a normal completed result. Cancellation also matters: the active engine is paused and detached from updates so an interrupted operation does not later publish a stale completed observation. The timeline provides an orderly user experience while the numbers still come from actual requests.
Three equal measurement windows
- Ping0–10 s
- Download10–20 s
- Upload20–30 s
Latency is sampled through exchanges
×The latency phase asks the library for a set of timing observations and uses its returned summary. That summary is displayed in milliseconds as ping. Jitter comes from the library's available variation summary. The page does not derive latency from download speed, and it does not turn a missing jitter field into zero. Timing and throughput are distinct properties even though they share parts of the same path.
A hypothetical connection can move a large amount of data efficiently while still taking a relatively long time for an individual exchange. Another can answer quickly but have limited transfer capacity. Those differences explain why a download score alone does not predict interactive responsiveness. The destination remains important: a measurement to a nearby service is not a promise about a distant game or call platform. This configuration does not collect loaded latency during the transfer phases, so its ping should not be described as a test of response delay under saturated download or upload. If that is the symptom you are investigating, preserve the concurrent workload and use an appropriate additional method rather than treating the quiet timing summary as complete evidence.
Download uses real payloads of different sizes
×The download phase requests actual data from the measurement endpoint. Its configured sequence includes smaller and larger payloads with finite request counts. Different sizes help produce observations across different transfer durations. The library applies its summary behavior and the integration's timing limits, so the final download figure should not be described as a simple division of an invented file size by the entire animated test time.
Very short requests can devote a large share of their interval to setup or scheduling effects, while longer requests can expose transfer behavior over a larger payload. That does not mean the largest request is always the only meaningful one or that the test promises a fully saturated link for a fixed number of seconds. The configured requests and deadlines determine what completes. A hypothetical fast connection may finish the sequence early; a slower one may encounter a phase deadline or limiting condition. The useful result is the library's throughput summary from valid measured requests. Understanding this prevents a common error in data usage estimates and explains why two tests with different request strategies can produce different figures on the same connection.
Upload measures the reverse direction with its own constraints
×The upload phase sends payloads from the browser to the measurement endpoint. It uses its own finite request sequence and phase window. A connection's outbound capacity can differ from inbound capacity because of the service design and conditions along the path. The device also has to supply the data and the receiving endpoint must handle it. The displayed upload is therefore an observed throughput summary for that direction.
A hypothetical household with a large download allowance and a smaller upload capacity may feel comfortable for viewing content but become constrained when several people send files. The full test separates those directions so the result can inform that question. A low upload value does not automatically identify the access provider as the limiting component, just as a high value does not guarantee every cloud service accepts data at that rate. Compare the relevant task and path, and note background uploads when taking a baseline. If the upload phase fails, preserve that failure rather than using the download result as a substitute. Completing one direction cannot certify the other, and the interface requires the relevant valid phase measurements before saving an ordinary completed result.
Summaries compress many observations
×A measurement library can collect several request observations and produce a summary according to its calculation rules. A summary is not necessarily the arithmetic average of every raw timing value you could find in the browser. Some observations may be unsuitable for a particular calculation, and the library's chosen summary can emphasize a defined part of the measured distribution. InternetSpeedGeo displays those summaries with unit conversion and formatting.
This is another reason not to reverse engineer a result from the animation alone. A hypothetical observer watching a gauge move cannot reconstruct which raw request measurements the library accepted or how their timings were summarized. The correct reference is the method and implemented configuration. When comparing services, differences in summarization can coexist with differences in server, request size and number of connections. A result is more interpretable when those choices are stated, but no single choice becomes universally best for every application. Keep the summary attached to the tool that produced it. For local comparisons, preserving the same method often matters more than arguing that a small numerical disagreement proves one test has discovered a uniquely true speed.
Distinguish the live display from the final record
×While a run is active, the interface can show updates from the summary currently available. Early values may change as requests complete and later observations contribute. Those updates help the visitor understand progress; they are not separate finished tests every time the gauge moves. Wait for completion before recording the ordinary final result or comparing it with a saved completed session.
A hypothetical observer might capture a screenshot during the download phase and another after upload finishes. If the earlier image shows a partial state or unavailable later metrics, it should be labelled accordingly. Do not combine the most favorable reading from each stage into a new result that the tool never produced. That would turn a sequence of updates into an invented composite. The same care applies when a run is cancelled: a visible intermediate number does not establish that all required measurements were accepted and saved.
This separation is useful when reporting a suspected interface problem. State whether the discrepancy appeared during the animation, at completion, in local history or in an export. Each is a different stage in the result's presentation. A hypothetical value that appears rounded differently in an export may concern formatting, while a field that vanishes before completion may reflect an incomplete measurement. Precise stage descriptions let the issue be checked without assuming that a cosmetic update changed the underlying traffic. The final record should remain an identifiable completed observation with its method and timestamp, rather than a collection of whichever transient figures happened to attract attention during the run.
The browser is part of the instrument
×A browser measures while sharing processor time, memory and network resources with the rest of the device. Background tabs, active applications, power management and extensions can change the conditions in which requests run and responses are processed. A precise timer improves elapsed time measurement, but it cannot make the browser independent of its environment.
Keep the page active and avoid heavy unrelated work when you want a baseline. A hypothetical device running a demanding local task may produce a different observation from the same device while idle, even on an unchanged connection. That possibility should be noted before assigning every difference to the provider. On a managed device, do not remove required security controls to simplify a test. Instead, document the environment and compare only authorized conditions. If a test improves in another browser, that is evidence that the broader browser environment changed; it does not immediately identify which extension, setting or scheduling behavior caused the difference. The instrument is useful precisely when its conditions are described, not when they are assumed away.
The local link can become the limiting segment
×A Wi-Fi link, wired adapter, dock, router port or mesh backhaul can constrain the complete path before traffic reaches the provider network. The browser's result contains that effect because it measures end to end. A plan with a higher stated access rate cannot force a slower local segment to carry more useful data than its current conditions allow.
A hypothetical wireless device far from the access point may improve when moved closer while the provider and endpoint remain the same. That supports investigating the local wireless path. An authorized wired comparison can reduce some radio uncertainty, though adapters and ports still matter. Check the active interface and any known local rate limitation before interpreting a result as a plan test. Avoid changing several devices at once; a new laptop on another cable in another room creates a broad setup comparison, not an isolated test of the provider. The Wi-Fi and Ethernet guide develops this reasoning in detail. The essential idea is that an end to end observation reveals the combined path, while careful comparison is needed to learn which segment is worth investigating next.
Endpoint and route influence the result
×The test endpoint is a participant in the measurement, not a neutral label that can be ignored. Its location in the network, current behavior and route from your provider affect what the browser observes. Another service can use a different route and have different constraints. Geographic closeness alone does not reveal every routing or processing detail.
For a hypothetical comparison, a large content platform may be well connected to your provider while a distant file server is not. A strong result to one does not prove the other is delivering incorrectly, and a weak result to another does not necessarily invalidate the first. Preserve the destination when reporting the difference. The map on InternetSpeedGeo provides geographic context; dragging it does not instruct the measurement engine to send data through the selected city. The separate ping tool also contacts this website rather than the full test endpoint. These distinctions explain many apparent contradictions between numbers that are actually observations of different paths. Use them to choose a relevant additional comparison instead of seeking a single number that stands for the entire internet.
Traffic already using the connection changes the experiment
×Other downloads, uploads, streams and updates can compete with the test. A busy connection can therefore produce a lower observed throughput than a quiet one without any permanent change in service capacity. The test itself also adds traffic, so it can influence other activities during the run. Decide whether your purpose is a quiet baseline or a view of ordinary busy conditions.
A hypothetical evening problem might coincide with both household backups and increased wider demand. Testing at different times without recording local activity leaves those explanations mixed. A comparison with a known upload paused, when authorized, can help determine whether the local workload is associated with the symptom. That does not make this configuration a loaded latency test or a complete queue diagnostic. It is an observational comparison with a stated change. If you want a provider discussion, collect conditions that the provider can interpret and distinguish deliberate load from baseline measurements. Avoid simultaneous speed tests on several devices when the goal is to compare their individual access; they may compete and alter the very path you hoped to hold constant.
Units and ideal transfer time are separate calculations
×The interface converts throughput summaries from bits per second to Mbps. To relate a rate to a file size, the units must be aligned. Eight bits form a byte, and file size conventions can differ between applications. An ideal duration calculation assumes a sustained rate and excludes other limiting work. It is useful for scale, not a guarantee of the time shown by a specific download or upload service.
For a hypothetical example, doubling a truly sustained transfer rate would halve the network transfer time for the same payload under otherwise identical assumptions. Real completion can include setup, pauses, verification or processing, so the total user visible duration may not halve. A plan percentage similarly compares an entered value with an observed value; it does not independently verify the plan or isolate responsibility for the gap. Keep these calculations labelled as interpretations of a measured input. They do not create additional observations. A result card, an ideal file time and a percentage can all be useful, but only when the reader can tell which number came from actual requests and which came from a formula applied afterward.
Failures and missing values are informative limits
×A failed phase means the required observation was not completed as expected. Possible causes include a connection change, endpoint restriction, browser interruption or other unavailable service behavior. The error does not automatically identify the cause. Preserve its stage and wording, and check whether ordinary connectivity and the intended network remained available.
Do not fill a missing value from another metric or assume a missing jitter field means perfect consistency. Likewise, a partial download value during a failed run does not establish a complete measurement record. A hypothetical support report can say that the upload phase failed under a named browser and connection while the earlier phase produced updates. That is a precise observation. Saying the provider has zero upload capacity would be a much stronger and unsupported conclusion. Missing data is often less visually satisfying than a full scorecard, but it protects the meaning of the output. The site uses completed measurement checks for stored history and separate acceptance rules for contributions, so the absence of a public aggregate can also have a different explanation from a failed local test.
Saving a result and contributing it are different steps
×When a full home test completes, the browser enriches the result with available context and attempts to retain it in local history. A separate request attempts to contribute eligible values for provider comparisons. The contribution can be rejected because of identity, provider, value, duplicate or repeat limit checks even when the local measurement is valid. Public averages are therefore not a guaranteed mirror of every row in Reports.
The local history is limited to the browser context and a maximum number of records. Provider comparisons use accepted submissions in a rolling ninety day period and group them by country, provider and selected mode. Historical eligible records can have different methods, and a voluntary sample is not a random customer survey. A hypothetical visitor who repeats a test to check a room may obtain useful local evidence without producing a new public row for every attempt. Do not confuse those outcomes. The privacy policy explains the information sent and retained, including the fact that clearing local history does not remove a server contribution. Understanding the pipeline helps interpret a measurement, its saved copy and the aggregate derived from accepted submissions as related but distinct objects.
Design a fair repeat test
×A repeat is most useful when it has a reason. Keep the same device, method, connection type and relevant location while checking whether the initial pattern recurs. If you intentionally change something, record that change and keep the other major conditions similar. Allow a previous run to finish rather than overlapping measurements that compete for capacity.
A hypothetical first result that is unusually low may be a transient event. A comparable repeat can show whether it persists, but several quick runs still represent a narrow time window. To investigate a recurring evening issue, observations across relevant periods with local activity noted are more informative than a dense sequence taken during a single minute. To investigate coverage, positions matter more than the calendar. Do not adopt a universal number of repeats as if it guarantees certainty for every question. The appropriate evidence depends on the decision and variability observed. Stop when the pattern is clear enough for a modest next step, or identify the specific missing comparison needed before making a stronger claim.
Explain a result in one defensible sentence
×A good summary names the browser connection, destination or method, time and observed pattern. It may say that comparable wired measurements were consistently higher than measurements from a distant wireless room, or that a remote application's difficulty was not reproduced by the Cloudflare path. Those statements are more precise than declaring the whole internet fast or slow.
Numerical scenarios in this guide are hypothetical illustrations, not field measurements conducted by the project. Your live completed result is the observation to interpret, and its scope should remain visible when shared. The methodology page provides the current configuration reference; Reports preserves local records; the guides on differing tests and plan expectations develop related comparisons. If you find an explanation that conflicts with the implementation, send the page and exact statement with supporting primary information to hello@internetspeedgeo.com. The aim is a measurement you can explain: what requests ran, what their summary means, which conditions could affect it and what comparison would make the next decision clearer. That understanding gives an ordinary browser test practical value without turning it into a certificate it cannot provide.
References and further reading
×Overview
Follow a measurement from the browser's request to the final summary, then learn why request size, timing, endpoints and local conditions affect what the result can establish. The worked scenarios are explicitly hypothetical teaching examples, not field measurements.