MoroccoMA
Investigate high ping and uneven response times
Describe the symptom before choosing a fix
×High ping is often used to describe several different experiences: a delay after an action, irregular movement in a game, audio that breaks up, a page that pauses before loading or an outright disconnection. Write down which experience occurs, in which application and under what conditions. This description determines whether a timing observation from a website is relevant and what additional evidence may be needed.
A hypothetical game that responds consistently but slowly differs from one that freezes unpredictably. A call that fails only while files are being sent differs from a call that fails on one device regardless of network load. Avoid beginning with a purchase or a broad settings change before distinguishing those cases. The objective is to find a condition that the symptom follows. A short record of the affected task, time, device, active connection and concurrent activity gives the investigation a stable starting point. You can then use the test as evidence for a bounded question instead of treating one score as a diagnosis of an entire provider or application.
Choose the right timing observation
×The full speed test reports latency and available jitter from the Cloudflare measurement library. The dedicated ping page times twelve HTTP responses to this website and summarizes their average, median and consecutive variation. A game or call platform can use a different destination and definition. Select the observation that helps your question, and keep each method labelled when you compare them.
If the symptom affects only a particular application, retain that application's diagnostic information when available. A low website reading cannot rule out a problem on another route, and a higher application reading does not automatically make the website value wrong. A hypothetical report can say that the website path remained regular while the application showed pauses, without concluding that the application server was definitely at fault. That distinction is essential because this site's current full test does not measure loaded latency or packet loss. It can contribute timing and throughput observations, but it cannot certify every property involved in a real time session. Start with what each tool actually measures and build the investigation from there.
Separate steady delay from variation
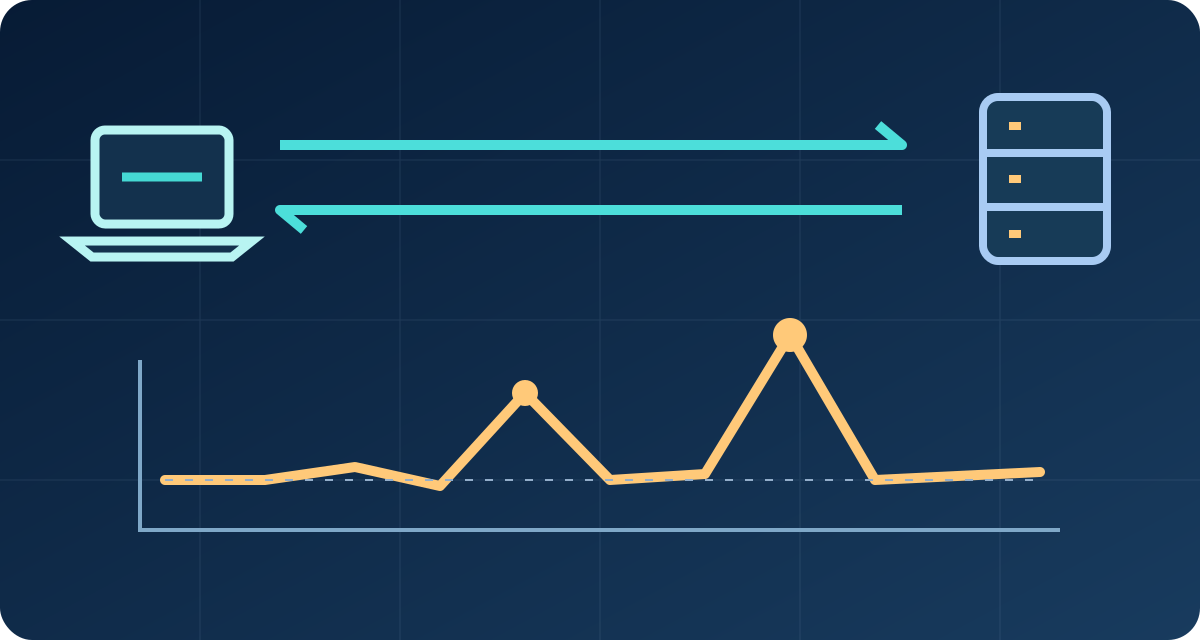
×A consistently long response time suggests a different pattern from mostly short responses interrupted by spikes. Inspect the average and median along with the ordered samples where available. If the average rises above the median, a few slow responses may be influencing it. If both remain elevated and samples are similar, delay may be steady within that short observation. Neither pattern identifies the cause by itself.
Jitter helps describe changing timing, but definitions vary between tools. The dedicated ping tool averages absolute differences between successive HTTP samples, while the full test uses the library's summary. A missing jitter value is not a favorable zero. In a hypothetical interactive session, steady delay can make actions feel consistently late, while sudden variation can cause bursts of uneven behavior. Applications may conceal or amplify those effects differently. Preserve the pattern in your notes instead of collapsing all symptoms into bad ping. This distinction helps decide whether to investigate path length and destination, intermittent local conditions, competing activity or a device that periodically stalls. It also makes a support conversation more precise.
Avoid reacting to a single transient spike
×An isolated spike can be important, especially if it coincides with an application pause, but its existence does not tell you whether the cause will recur. Preserve the timing and context, then choose a limited comparable observation. If it does not recur, report that uncertainty rather than declaring the problem solved or permanently present. A hypothetical one time interruption during a device update should not be generalized to every ordinary session without further evidence.
Also consider the cost of a proposed intervention. Restarting a shared router can interrupt active work, changing several radio settings can alter other devices' connections, and removing a managed tool can violate the network owner's requirements. A transient observation is a reason to gather context before taking a disruptive step. Where a reversible local comparison is available, use it to test a specific hypothesis and preserve the prior state. This does not mean ignoring recurring symptoms; it means matching the intervention to the evidence. If serious disruption persists, involve the responsible administrator or provider with the record you have. A cautious conclusion about an isolated event is often more useful than a dramatic fix whose relationship to the symptom cannot be assessed afterward.
Establish a quiet local baseline
×Choose a moment when you can reduce avoidable competing traffic without disrupting other people. Pause an authorized backup or large transfer if appropriate, keep the page active and make sure the device remains awake. Note the connection type, VPN state and relevant room or broad position. These conditions do not make the entire internet quiet; they reduce some known local differences.
Run a limited observation and record its completed status. If it fails, preserve the error separately rather than assigning a packet loss percentage. A hypothetical baseline might show regular responses while the ordinary busy period does not. That would motivate a comparison of activity, not prove that the provider is universally healthy. If the baseline is already uneven, a local link or device comparison becomes useful. Do not change several settings before collecting the starting observation, because that removes the context needed to assess whether a later improvement relates to the intended change. A baseline is a named condition against which another observation can be compared, not a magical perfect state or a certificate of what every future session will experience.
Use a wired comparison when available
×An authorized Ethernet comparison on the same device can reduce uncertainty about the wireless segment. Verify that Ethernet is active and note any adapter or dock. Keep the destination and broad timing conditions similar. Avoid running the wired and wireless tests simultaneously, because competition between them changes the conditions. If you cannot make a wired comparison, state that limitation and use another controlled local comparison instead.
A hypothetical pattern of stable wired responses and variable wireless responses supports attention to the local radio environment or access arrangement. It does not name a particular channel, antenna or product as the cause. If both show similar problems, investigate conditions shared by the two paths, including the device, router, upstream connection and endpoint. A wired path can still have limitations, so it should not be treated as proof that all local equipment is perfect. The value of the comparison comes from changing one relevant segment. Record what changed and what remained the same, then decide whether another device or another authorized time period can narrow the remaining possibilities.
Test wireless placement before changing advanced settings
×Move the same device to a position with a clearer path to the access point while keeping the rest of the setup as similar as practical. Record whether the symptom and timing pattern change. Walls, distance, competing radio activity and the access point's own upstream link can all matter. Strong signal bars alone do not guarantee an unconstrained path to the internet.
A hypothetical improvement near the main router can justify examining placement or coverage in the original room. If a mesh node is involved, remember that the device's link to that node is only one segment; the node's link onward may also matter. Do not buy an extender solely because the word jitter appears on a screen. A poorly placed additional node can add complexity without addressing the observed limit. Start with evidence about where the pattern occurs and consult the equipment's official guidance for authorized adjustments. If you change a setting, preserve the previous value so the comparison can be understood and reversed where appropriate. Routine placement checks often provide useful information before more intrusive configuration changes are considered.
Check whether concurrent uploads track the symptom
×Outbound transfers can share a constrained upload path with calls, game traffic and request acknowledgments. When traffic queues, interactive exchanges may wait even if the connection can still move substantial data. This is one reason a good download number does not settle an intermittent responsiveness problem. Record the activity happening at the moment of the symptom.
For a hypothetical call investigation, compare an authorized period with a backup running and a comparable period after it is paused. Watch whether the application symptom changes and keep any timing observations labelled by condition. The current test does not supply a loaded latency score, so do not claim that this comparison measured a standardized bufferbloat grade. It is evidence that a workload may be associated with the problem. If that association repeats, scheduling transfers or reviewing authorized queue management options with the equipment owner may be relevant. If it does not, retain the finding and investigate another condition. A hypothesis becomes useful when it predicts a comparison you can check, rather than when it provides a technical sounding explanation for every pause.
Treat router traffic management as a targeted option
×Some routers offer traffic prioritization or queue management features that may help when competing traffic causes delay. The appropriate feature and configuration depend on the equipment and connection. Do not assume a setting with a promising name is enabled, suitable or harmless for every network. Consult the manufacturer's current instructions and involve the administrator when the router is managed by someone else.
A hypothetical improvement after an authorized setting change should be compared with the previous condition under similar load. Record what changed and whether throughput or another task was affected. A feature can involve tradeoffs, so the goal is the application's usable behavior rather than maximizing every number independently. Do not reset a router to factory defaults as a casual first step; that can erase configuration and interrupt service. If the device belongs to a provider, ask about its supported process. This guide identifies a possible area for investigation when the evidence points toward queueing, but it does not infer a diagnosis or prescribe settings without knowing the equipment. A measured pattern should lead the configuration decision, with a clear way to assess the result.
Account for VPN and routing changes
×A VPN can change the route, exit network and processing involved in reaching a service. That can affect delay and variation. If it is required for work or another managed purpose, follow the applicable rules instead of disabling it to chase a lower number. Where an approved comparison is possible, note the VPN state and selected exit context alongside the measurement.
A hypothetical reduction in website latency after an authorized route change establishes a difference between those tested paths. It does not prove that the VPN is defective or that every application will improve by the same amount. A work application may require the route or use a different destination. Similarly, an IP city estimate is not a complete route trace. Use the lookup to understand outward context, then preserve the actual service and method in your report. If the problem appears only through a required tunnel, the organization operating it may have relevant diagnostics. Provide a concise condition comparison without disclosing credentials, tokens or confidential internal addresses unnecessarily. The goal is to identify the path associated with the symptom while respecting why that path exists.
Investigate an application specific problem as such
×If only one application is affected, inspect its own server region, connection status and diagnostic display where available. A nearby measurement endpoint and a remote application can behave differently without contradiction. The application may also be waiting on its own processing or device rendering, which the website's network result does not directly measure.
A hypothetical game with one slow server region may improve on another officially available region, but changing the region can affect who you play with or how the application works. Follow the application's intended controls rather than using unsupported routing tricks. For calls, note whether every participant is affected or only one direction of communication appears poor. These observations can help the service's support team ask a better question. Do not declare the provider innocent or the application guilty solely because one speed test looks good. State that a particular tested path did not reproduce the problem, then preserve the application's symptom, destination and time. That is a meaningful narrowing of evidence without overclaiming a fault location.
Check the device's workload and power state
×The device must run the browser, process responses and operate the application you care about. Heavy local work, thermal constraints, power management or an inactive browser window can change the conditions. If the connection symptom appears on only one device, compare its behavior with a suitable authorized alternative while keeping the network context similar.
A hypothetical laptop that pauses during a demanding local task may show timing variation even though another device on the same path does not. That suggests investigating the original device's conditions, but it does not immediately identify a particular process or component. Record whether the device was on battery, whether a major update was running and whether the test remained active. Avoid disabling required security software merely to remove a variable. A normal restart or closing unneeded applications can be a relevant reversible comparison when it does not interrupt important work, but note that several conditions may change at once. The website does not inventory every local cause. Its timing evidence becomes more useful when paired with a careful account of what the device was doing.
Understand mobile variability before drawing a broad conclusion
×Mobile access can vary with radio conditions, movement, handovers and shared capacity. A short stationary observation and a moving session can therefore represent different conditions. When investigating a mobile problem, note whether the device moved, whether it switched access modes and whether tethering added another local link. A public IP estimate may describe a regional exit rather than the nearby radio site.
A hypothetical improvement after moving indoors or outdoors is useful evidence about that tested position, but it does not automatically predict performance across an entire neighborhood. Similarly, switching from mobile data to Wi-Fi changes the upstream path and cannot isolate a phone defect by itself. Keep the comparison's scope modest. If a recurring issue depends on a particular place or time, collect a few relevant observations with those conditions clearly labelled and contact the appropriate provider when needed. Do not run continuous bandwidth tests while travelling or on a small allowance merely to generate a dense record. The most useful data describes the circumstance associated with the symptom and identifies which change deserves further investigation.
Do not make DNS the default explanation for every delay
×Name resolution can affect the beginning of a connection, but it is not the same as ongoing response timing or sustained throughput once communication is established. A slow first page opening, a game that becomes uneven after an hour and a low upload rate are not automatically the same problem. Describe when the delay occurs in the task before changing resolver settings.
A hypothetical website that pauses before any content appears may justify examining connection setup, including DNS among other possibilities. The symptom alone still does not prove the cause. If a managed network provides specific resolver settings, use its support process rather than replacing them without authorization. A different resolver is not a universal way to lower every application's ping, because the eventual endpoint and route still matter. This guide encourages specific hypotheses: which stage would the proposed change affect, and what comparison would demonstrate that effect? If those questions cannot be answered, collect clearer observations first. Avoid a sequence of popular tweaks whose individual effects cannot be separated afterward.
Interpret errors and absent measurements carefully
×An incomplete test or missing field limits the conclusion. The dedicated HTTP ping tool stops when a request fails, so unfilled sample positions are not evidence of packets sent and lost. The full test does not measure packet loss, and missing jitter is not equivalent to perfectly steady timing. Preserve the exact failure, stage and connection context instead of converting absence into a number.
A hypothetical failed sequence can be described as several successful responses followed by an unavailable request. It cannot support a precise loss percentage for the entire connection. Check whether basic browsing still works and whether the same request is restricted on the network. If a managed policy explains the failure, respect that boundary. If the failure repeats across comparable authorized conditions, report that pattern with the browser and time. Acknowledging an unmeasured property does not weaken the report; it makes the evidence more trustworthy. The next diagnostic should be chosen because it can answer the unresolved question, not because a blank field creates pressure to supply a reassuring or alarming score.
Keep a compact investigation log
×Record each meaningful comparison with its time, device, connection, VPN state, concurrent activity and completed results or errors. Add the application's symptom and whether it occurred during the measurement. Keep observed facts separate from suspected causes. Reports can retain completed speed measurements in this browser, but it does not automatically record every failed attempt or environmental detail.
For a hypothetical sequence, a log might show a quiet wired baseline, a comparable wireless observation and an ordinary busy period with a known upload. The labels make it possible to see which condition the symptom follows. Do not merge values from the dedicated HTTP tool and full speed test into an unnamed ping average, because their destinations and methods differ. Export important records before clearing site data and redact unrelated identifiers before sharing. A short, coherent log is easier for an administrator or provider to interpret than many screenshots without context. It also helps you stop repeating comparisons that already produced the same useful result and focus on the remaining uncertainty.
Escalate with a bounded question
×Contact the organization that can act on the condition your evidence identifies. A managed network issue belongs with its administrator, a subscription or recurring access issue with the provider, and a service specific problem with the application's support. InternetSpeedGeo can receive reports about its own tools or explanations at hello@internetspeedgeo.com, but it cannot repair another organization's infrastructure.
A hypothetical provider message can describe a recurring pattern under an authorized wired baseline and ask what further diagnostics the provider needs. An application message can explain that the symptom occurs on a named service while another measured path behaves differently. Neither needs an accusation or a claim that the website certified the fault. Include dates, units and a minimal relevant extract. Avoid passwords, payment details or complete configuration files unless an appropriate process specifically requires limited information. State the outcome you want, such as help identifying the cause or checking a supported setting. A clear question gives the recipient a useful next step and preserves the limits of the evidence instead of asking them to accept an unsupported diagnosis.
Recognize when the investigation has answered enough
×You do not need perfect knowledge of every hop to make a modest useful change. If a repeatable local placement comparison improves the task, that may be enough to choose the better position. If a permitted schedule change prevents uploads from conflicting with calls, preserve that practical result while acknowledging that the exact internal queue behavior remains unmeasured. If no comparison isolates the issue, identify the missing evidence and involve the responsible support channel.
Avoid continuing to tweak after a useful stable outcome merely to make a score smaller. Each additional change can introduce another variable and make the earlier conclusion harder to reproduce. A hypothetical improvement in website ping that does not improve the actual application may not be the relevant success criterion. Return to the original symptom and assess whether it changed under ordinary use. High delay and variation are properties to investigate, not labels that dictate a universal purchase or setting. A careful sequence of observations, one change at a time where practical, provides a defensible path from a frustrating experience to a proportionate next action.
References and further reading
×Overview
A useful latency investigation separates steady delay, changing delay, application symptoms and missing measurements. Work through controlled comparisons before deciding which setting, device or provider needs attention. The examples are hypothetical teaching cases, not customer measurements.